ARCHES: An Agent-Based Refinement Cycle for Hierarchical Synthesis of Sound Effect for Variety Shows
Wentao Lei, Li Liu
The Hong Kong University of Science and Technology (Guangzhou), China
Abstract: Sound effect for variety shows can greatly improve viewer engagement, which currently relies on a labor-intensive manual process. This approach is heavily dependent on the experience of human editors. While recent advancements in audio generation have shown promise, they struggle to meet the unique demands of variety shows, exhibiting critical limitations in temporal precision, content diversity, and contextual understanding. To overcome these limitations, we propose ARCHES (Agent-based Refinement Cycle for Hierarchical Synthesis), a novel framework that leverages multi-agent collaboration and retrieval-augmented generation to automatically produce high-quality, contextually appropriate sound effects. The framework contains an iterative workflow of planning, generation, and refinement. The cores of this framework are two innovative modules: the Auditory Unified Retrieval Augmentation (AURA) module, and the Adaptive eXpert Intelligent Switch (AXIS) module. To validate our approach, we constructed the first large-scale, fine-grained dataset for this task, the Variety Show Sound Effect Benchmark (VSSE-Bench). Extensive experiments demonstrate that ARCHES significantly outperforms state-of-the-art (SOTA) baselines on both objective and subjective metrics.
Framework Overview
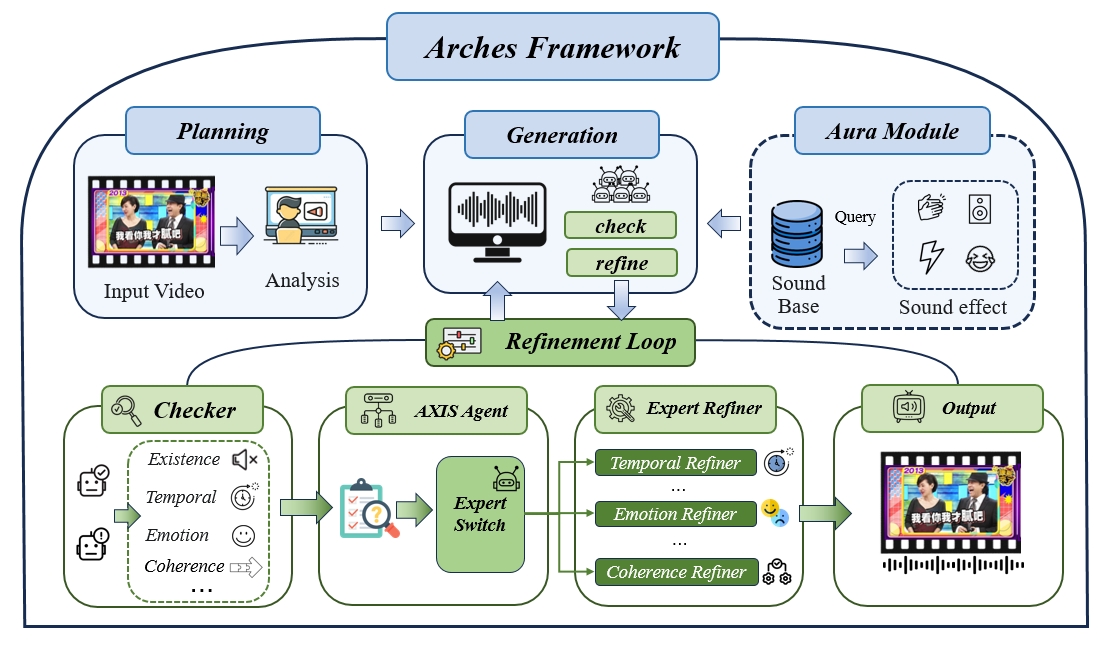
The ARCHES framework consists of three main stages: Planning, Generation, and Refinement. The Planning Agent analyzes input video content to identify key moments requiring audio enhancement. The Generation Agent performs conditional audio synthesis using the AURA module for retrieval-augmented generation. The Refinement loop includes a Checker Agent for evaluation and the AXIS module for intelligent task routing to specialized agents.
Key Contributions
- We propose ARCHES, a novel framework that introduces a hierarchical, agent-based workflow of design, generation, and iterative refinement to sound effect synthesis for variety shows.
- We design two novel modules: AURA, a retrieval-augmented module to enhance content diversity, and AXIS, a self-routing mechanism that intelligently dispatches tasks to specialized agents.
- We construct and will release the first large-scale, fine-grained dataset for variety show sound generation, the Variety Show Sound Effect Benchmark (VSSE-Bench).
Experimental Results
- ARCHES significantly outperforms all baseline models across both objective and subjective metrics on the VSSE-Bench dataset.
- Notably, it achieves a 20% reduction in Synchronization Error compared to the next-best model, highlighting the effectiveness of the Temporal Dynamics Agent.
- High scores in human evaluation study validate the model's ability to generate creative and contextually appropriate sound effects.
Conclusion
In this work, we introduce ARCHES, a novel framework designed to resolve the critical challenges of sound effect generation for variety shows. ARCHES contains three key modules: the AURA module, which leverages multi-modal retrieval to provide rich contextual sound effect material, and the AXIS module, which dynamically routes tasks to specialized agents for efficient refinement. The CEB records successful workflow and guides the full generation. Extensive experiments demonstrate that our proposed framework quantitatively and qualitatively outperforms current SOTA methods. Future work will investigate applying this agent-based refinement cycle to a cross-modal audio-visual generation of Variety Shows.
Demo Samples: Sound Effect Generation
This section presents video clips from variety shows and the corresponding sound effects generated by different models.
| Original Video | ARCHES (Ours) | MMAudio | FoleyCrafter | HunyuanVideo-Foley |
|---|---|---|---|---|
Disclaimer
The content provided above is for academic purposes only and is intended to demonstrate technical capabilities. If you have any concerns, please contact us.